We’ve been working on something we call “SemOps” (like DevOps but for Semantic Technology + IT Operations). The basic idea is how can we create a pipeline to go from proposed enterprise ontology or taxonomy enhancements to “in-production” as frictionlessly as possible.
As so often happens, when we shine the Semantic Light on a topic area, we see things anew. In this very circuitous way, we’ve come to some observations and benefits that we think will be of interest even to those who aren’t on the Semantic path.
DevOps for Data People
If you’re completely on the data side, you may not be aware of what developers are doing these days. Most mature development teams have deployed some version of DevOps (Software Development + IT Operations) along with CI/CD (Continuous Integration / Continuous Deployment).
To understand what they are doing it helps to harken back to what preceded DevOps and CI/CD. Once upon a time, software was delivered via the waterfall methodology. Months or occasionally years would be spent getting the requirements for a project “just right.” The belief was that if you didn’t get the requirements right up front, the cost to add even a single new feature would cost 40 times what it would cost if the requirement were identified up front. It turns out there was some good data on this cost factor, and it still casts its shadow any time you try to make a modification to a packaged enterprise application, 40 x is a reasonable benchmark compared to what it would cost to implement that feature outside the package. This as a side note is the economics that creates the vast number of “satellite systems” that seem to spring up alongside large packaged applications.
Once the requirements were signed off on, the design began (more months or years) then coding (more months or years) finally systems testing (more months or years). Then the big conversion weekend, the system goes into production, tee shirts are handed out to the survivors and the system becomes IT Operations problem.
There really was only ever, one “move to production” and few thought it worthwhile to invest the energy in making this more efficient. Most sane people, once they’d stayed up all night on a conversion weekend, were loath to sign up for another, and it certainly didn’t occur to them to find out a way to make it better.
Then agile came along. One of the tenets of agile was that you always had a working version that you could, in theory, push to production. In the early days it wasn’t that people were pushing to production on any frequent schedule, but the fact that you always could was a good discipline to avoid technical debt and straying off building hypothetical components.
Over time, the idea that you could push to production became the idea that you should. As people invested more and more in their unit testing and regression testing, and pipelines to move from dev to QA to production, people became used to the idea of pushing small incremental changes into production systems. That was the birth of DevOps and CI/CD. In mature organizations like Google and Amazon, new versions of their software are being pushed to production many times per day (some reports say many times per second, but this may be hyperbole).
The reason I bring it up is because there are some things in there that we expect to duplicate with SemOps, and some that we already have with data (as I was writing this sentence, I was tempted to write “DataOps” and I thought: “is there such a thing?”) A nanosecond of googling later and I found this extremely well written article on the topic from our friends at DataKitchen. They are focusing more on the data analytics part of the enterprise, which is a hugely important area. The points I was going to make were more focused on the data source end of the pipeline, but the two ideas tie together nicely.
Capital Costs v Operational Costs
In some ways what happened on the way to DevOps and CI/CD was a shift from operational costs to capital costs (I don’t think that’s what motivated it, but I think that is a good way to characterize what happened). In the old days, when someone introduced a change to an existing system, they ran a suite of tests (by hand!) against the database to make sure nothing was adversely affected. The UI tests were all done by hand. As the world’s most interesting man puts it, “I don’t always test my code. But when I do, I do it in production.”
This approach incurs a lot of operational cost each time code is moved to production. It also has been proven to miss a lot of bugs.
Having a rigorous unit and regression test suite, is a large one-time investment, both of infrastructure, but mostly building the tests. It is therefore a capital cost. It is not unusual for a mature modern system to have half as much test code as actual code. But the payoff, as with most capital investments, is it makes each individual turnover cheaper and safer.
In a moment we’re going to look long and hard at the capital costs we’re already incurring, and how to think about that tradeoff going forward.
Data Governance and Software Development
We’re going to spend some time with the similarities and differences between data governance and software development, especially because we’re going to try to figure out when do changes in ontologies more resemble Data Governance and when does it more resemble Software Development.
In order to make these comparisons I’m going to have to abstract what both groups are doing in a way that they are comparable. This is harder than it sounds. Or easier than it sounds, depending on your point of view. If your point of view is these two disciplines are so different that no sensible comparison could be made, then what I’m going to outline is easier than the impossible task of reconciling two irreconcilables. On the other hand, if you think, “they really are kind-of doing the same thing” then you’ll find this a bit harder than it first sounds.
What makes this harder, as far as I’m concerned, is that there is a great deal of literature on Data Governance, but not much that really gets specific about what people are doing when they do “Data Governance.” I went back and re-read my (DAMA International) DMBOK Chapter 3 on Data Governance and while there is a great deal of the strategic importance and organizational considerations it was light on what Data Governance people are actually doing. Same with many other sources I consulted. I’m hoping someone reading this will come up with some helpful suggestions, and if I’m really lucky they will align with what I’m describing here. Meanwhile, I’m stuck putting forward my own framework.
A lot of what I’m about to suggest here is derived more from my experience and observations working side by side with Data Governance professionals. We encounter all kinds of Data Stewards, Data Custodians, Metadata Managers, Data Council Leaders all the way up to Chief Data Officers. What I’m going to outline is my impression of what I think they are doing.
Some of what they are doing is just being an expert in a particular subdomain and knowing where the credible sources are. This is a valuable role, especially in companies that have let their data landscape grow in an uncontrolled fashion and they have thousands of potential sources of data. We rely on them when we build ontologies, because knowing what all the data means has become a highly decentralized function. But this isn’t a “doing” in the sense that I want to explore here. Being an expert and being a go-to resource isn’t a “doing” kind of thing.
My thesis is that in both Data Management and IT Operations the landscape already exists. The data landscape and the code landscape. The thousands of applications and thousands of databases already exist. Governance is not so much about creating new applications or data sources. The firm tends to create projects to do that. Governance of code and data, is more about dealing with what exists and performing the following activities:
- Quality—Assessing and attempting to continually improve the overall quality of the data or the code.
- Allowing/“Permissioning”—Creating mechanisms for determining who gets to make changes to data or code, and how those changes are prioritized
- Predicting side effects—This is about doing impact analysis to determine if a given change will have a detrimental effect on the overall landscape (data or code)
- Constructive change—Sometimes a proposed change requires knock-on effects. Changing the name of a schema element may require code, queries, or documentation be changed to accommodate it. This task is about making those upgrades to a system that is in use.
- Traceability—A great deal of compliance is about proving that all changes were authorized. Whether this is Sarbanes Oxley wanting to know the provenance of key data elements on financial reports, or cyber-security wanting to know that all changes to code were authorized and unlikely to contain viruses, this is the discipline of traceability.
This is what I think governance means at the ground level. There are many strategic reasons to want to do this, there are many ways to organize for it, but at some point I think we need to execute these basic functions. I think the functions exist on the data side and the code side, and by extension on the semantic side. They exist at the data level and at the metadata level.
What is fascinating to me is:
- How and why have data professionals and software developers evolved different strategies to satisfy these five basic functions
- What can ontologists learn from this, and therefore, what will SemOps ultimately look like?
We’ll take up each of the five activities in turn and compare and contrast how each activity is performed in DevOps and Data Governance to inform our choices in SemOps.
But before we do, I want to cover one more difference: how the artifacts scale under management.
Code
There isn’t any obvious hierarchy to code, from abstract to concrete or general to specific, as there is in data and semantics. It’s pretty much just a bunch of code, partitioned by silos. Some of it you bought, some you built, and some you rent through SaaS (Software as a Service).
Each of these silos represents, often, a lot of code. Something as simple as QuickBooks is 10 million lines of code. SAP is hundreds of millions. Most in-house software is not as bloated as most packages or software services; still, it isn’t unusual to have millions of lines of code in an in-house developed project (much of it is in libraries that were copied in, but it still represents complexity to be managed). The typical large enterprise is managing billions of lines of code.
The only thing that makes this remotely manageable is, paradoxically, the thing that makes it so problematic: isolating each codebase in its own silo. Within a silo, the developer’s job is to not introduce something that will break the silo and to not introduce something that will break the often fragile “integration” with the other silos.
Data and Metadata
There is a hierarchy to data that we can leverage for its governance. The main distinction is between data and metadata.
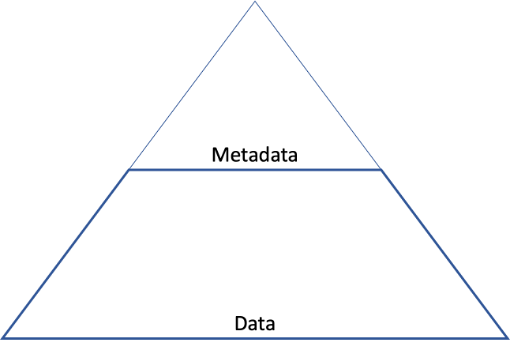
There is almost always more data than metadata. More rows than columns. But in many large enterprises there is far, far more metadata than anyone could possibly guess. We were privy to a project to inventory the metadata for a large company, who shall go nameless. At the end of the profiling, it was discovered that there were 200 million columns under management in the sum total of the firm. This is columns not rows. No doubt there were billions of rows in all their data.
There are also other levels that people often introduce to help with the management of this pyramid. People often separate Reference data (e.g., codes and geographies) and Master data (slower changing data about customers, vendors, employees, and products).
These distinctions help, but even as the data governance people are trying to get their arms around this, the data scientists show up with “Big Data.” Think of big data being below the bottom of this pyramid. Typically, it is even more voluminous, and usually has only the most ad hoc metadata (the “keys” in the “key/value pairs” in the deeply nested json data structures are metadata, sort of, but you are left guessing what these short cryptic labels actually mean).
Knowledge Graph / Data-Centric
The knowledge graph is also layered, but there are several quite interesting aspects of its layering that come to the fore for our governance, and SemOps. Done well, the first is that the ontology that holds the whole thing together is “human scale.” Unlike 200 million bits of metadata or even 10,000 applications, the top ontology is often 400–600 concepts. Not only is it understandable at that level, but it also doesn’t change as often. These are 400–600 enduring themes that change slowly.

The taxonomy is usually thousands to tens of thousands of concepts, but unlike the ontology, they have little structure or complexity, and it is rare (but occasional) that developers hard code to the taxonomy terms (they do this all the time with the ontology, even though this isn’t best practice).
We show the data segmented here to indicate that unlike data warehouses, and data lakes, there isn’t a need to co-locate all the data, and as we’ll see later there are some great advantages in performance and security for not co-locating all the data.
Ok, now we’re ready to start looking at how governance is different in our three domains, by our five activities.
Quality
The primary approaches to detecting quality issues in each of the sub domains are:
| Software | Data / Metadata | Knowledge Graph / Data-Centric |
|---|---|---|
| Regression testing | Statistics and conformance between metadata and data | Inference, patterns, hygiene queries |
Software developers typically build vast suites of tests. Unit tests, regression tests, systems tests, and the like. Developers know it is futile to try to predict what is going to break when a change is made. Make the change, run the tests, repair, if necessary. Part of this is because how little layering or leveling there is in software code. Some development shops are good at “design by contract” around their APIs and can limit the side effects, but most are not.
Most enterprises live with acceptable levels of data and metadata quality. They know they live with “dirty data,” unnecessary duplicates, missing data, inconsistencies, and the like. It is very hard to get ahead on data quality, there is so much of it. Data quality ends up being dashboards, where earnest people try to keep a trend line (i.e., orders taken without credit report on file or addresses without postal codes) moving in the right direction.
In the knowledge graph world, the first quality approach is rigorous socialization. The ontology is small enough that it can be reviewed, in great detail, by technologists as well as subject matter experts. Inspection is also a good technique in coding, but the volume of changes in code bases is typically so much greater, and the ability for non-technical people to contribute to the review is limited.
By using formal axioms in the definition of concepts, the system (a “reasoner” or “inference engine”) can detect a large range of logical errors that would not be caught in a traditional system until much later in the process. Also, we are finding that just putting data in a graph gives easy-to-write-and-execute queries that can detect anomalous patterns.
Allowing/“Permission-ing”
Authorization is the process of deciding who can see and modify the code or the data. The other side of security, authentication (how do we know you are who you claim to be) is not so different between the three realms, but the authorization is different.
| Software | Data / Metadata | Knowledge Graph / Data-Centric |
|---|---|---|
| Few roles, automated turnover process | Entitlements, and many hard coded application specific roles. | Roles and rules derived from your real world relationships including your relationship to the data. |
It is essential that unauthorized actors do not get into the codebase. Getting into the codebase is a vector where all kinds of bad things can happen. Generally, developers have a few well-defined roles (e.g., Developer, QA, Move-to-Production) with no overlap in duties. Developers code in a partitioned environment but do not have permission to move their code to the QA environment. The QA developers independently verify that the code works and does not introduce stray code into the codebase; then they approve the code to move to production, at which point the Move-to-Production team takes over.
For metadata, the process is much more like code, in that a change to metadata can easily break production code. If you drop a table that a program relies on, the program will fail.
Data is different. The authorization rules for any given application system are designed as the application is being designed or implemented. The most common approach is to invent a series of “roles,” such as Admin, AR Entry, and Vendor Management. A system admin assigns people to these roles (often in records called, “entitlements”) and the developer introspects the authenticated users, picks up their entitlements and grants them or denies them access either to the use case or occasionally more directly to the data (as defined by its metadata). The data and system entitlements are almost always limited to an individual application. Unfortunately, the same data and same functions are often present in other applications and it is a very difficult discipline to apply the rules consistently over many applications and users.
Knowledge Graphs open up new possibilities, but they also raise the stakes considerably. Even if all the data isn’t collocated, often the shared meaning and federated queries mean that it is easy to wander your way into data you shouldn’t have access to. We have just begun working on architectures and patterns that take advantage of our ability to know someone’s real life roles (if you filed an insurance claim, you’re a “claimant”) and their relationship to specific data (being a claimant should only give you access to your claims, being a claims manager should give you access to a much wider set of claims).
Separating especially sensitive data to repositories with very limited access is another way to implement authorization control in a Knowledge Graph.
Predicting Side Effects
Predicting side effects is about contemplating a change, and then trying to determine what else will be affected.
| Software | Data / Metadata | Knowledge Graph / Data-Centric |
|---|---|---|
| Very little attempt to predict, change and test | Ultra conservative in change making as most metadata changes break code | Use the graph to predict the change |
Most developers have a pretty good sense what kinds of changes will break things. But they use this knowledge more to predict effort than specific impact. In practice, they seem to make the change and run the test. For example, if a change later in production is found to create defects, the approach is to write another test that would have detected that problem.
Metadata change is very slow. Data modelers know that once there is a body of code dependent on a set of metadata, almost any change will have a major ripple effect. You won’t necessarily know the impact until you make the change as the cause of the failure is often references to metadata in code. My observation is that in a typical business application, half of the code directly or indirectly addresses the metadata.
The data is easy. No one contemplates regression testing or impact analysis when they are changing data. When you add a new contact to your contact management system you don’t expect the system to crash. You rely on the fact that validation and constraint management coded into the application will prevent you from entering data that would break the system.
In a knowledge graph system, especially one that relies heavily on model driven development, most of the dependencies are right there in the graph. If you write a query that refers to Employee and Salary, your query persistence routine can easily parse the query text and attach a link from the query to the two concepts. This way, when you consider changing something about Person or Salary, it is easy to find the parts of the system that will be affected.
Constructive Change
Here the issue is, if you decide to make a change, and your impact analysis tells you what will be affected, can the system help with the change.
| Software | Data / Metadata | Knowledge Graph / Data-Centric |
|---|---|---|
| Some refactoring | The metadata side can be scripted, but the code will have to be fixed by hand | There are some scripts that can be packaged with the change |
For code, we mostly just have renaming and refactoring. If someone decides to change Employee to Personnel, the coder will have a lot of find and replace style refactoring.
Some of the data / metadata changes can be automated. If you decide that a previously optional field is to become required, you will have to pick a suitable default and run a script to update the data to agree with the metadata.
In the Knowledge Graph world, we often find that quite significant changes can be packaged with an update-in-place script (a SPARQL update query, typically) and pushed with the change.
Traceability
Finally, one part of governance is: Can we assure ourselves that we can account for all the changes in the system?
| Software | Data / Metadata | Knowledge Graph / Data-Centric |
|---|---|---|
| Change logs | Metadata change logs | Provenance |
In a modern development environment, every line of code is associated with a specific change of “delta.” Code repositories are able to present the change, what was changed along with it, who made the change, when it was made, when it was pushed to production, etc.
Data and metadata systems have something similar, although they are nowhere near as consistent. Each application may log data its own way, and each Database Management System logs changes to metadata in their own way.
Knowledge graphs rely on provenance, which is a rich vocabulary for tracing a change all the way back to its source. Provenance, in the real world, is about detecting whether the chain of custody for a piece of artwork is legitimate (i.e., there is a continual record of ownership, and there haven’t been episodes when it was stolen or plundered). Similarly, provenance is used to detect blood diamonds to trace the chain of ownership back to a mine that either is or isn’t known for cruelty to its workers.
For the knowledge graph we can determine where an individual triple came from. We can also determine if that triple was generated from an analytic step, what the steps were, what input it relied on, and so on, back to the equivalent of the diamond mine.
Summary
By disassembling DevOps, Data Governance and rethinking what a SemOps platform needs to do, we think we have outlined a practice that may mean that we can make changes to Ontologies, Taxonomies, or even model driven applications, predict with a great deal of confidence what the side effects will be, and arrange to push it to production, with little human intervention.
Unlike Data Governance with its army of Data Stewards, Quality Assurance Professionals, and Change Managers, we think Knowledge Graph based systems will be human-scaled and much easier to manage.
Unlike code, we believe that a mature Knowledge Graph environment will not have hundreds of thousands of lines of test code to be run every time a change is made, and that if we can predict and introduce the constructive changes, we have a path to continuous evolution.
First published on TDAN.com in two parts, in December 2020 and March 2021.